Google Search has just updated its favicon documentation to now specify that Googlebot must be able to follow redirects from the homepage to the page where the favicon is specified. The document also explicitly says that these URLs must not be blocked by robots.txt or other means.
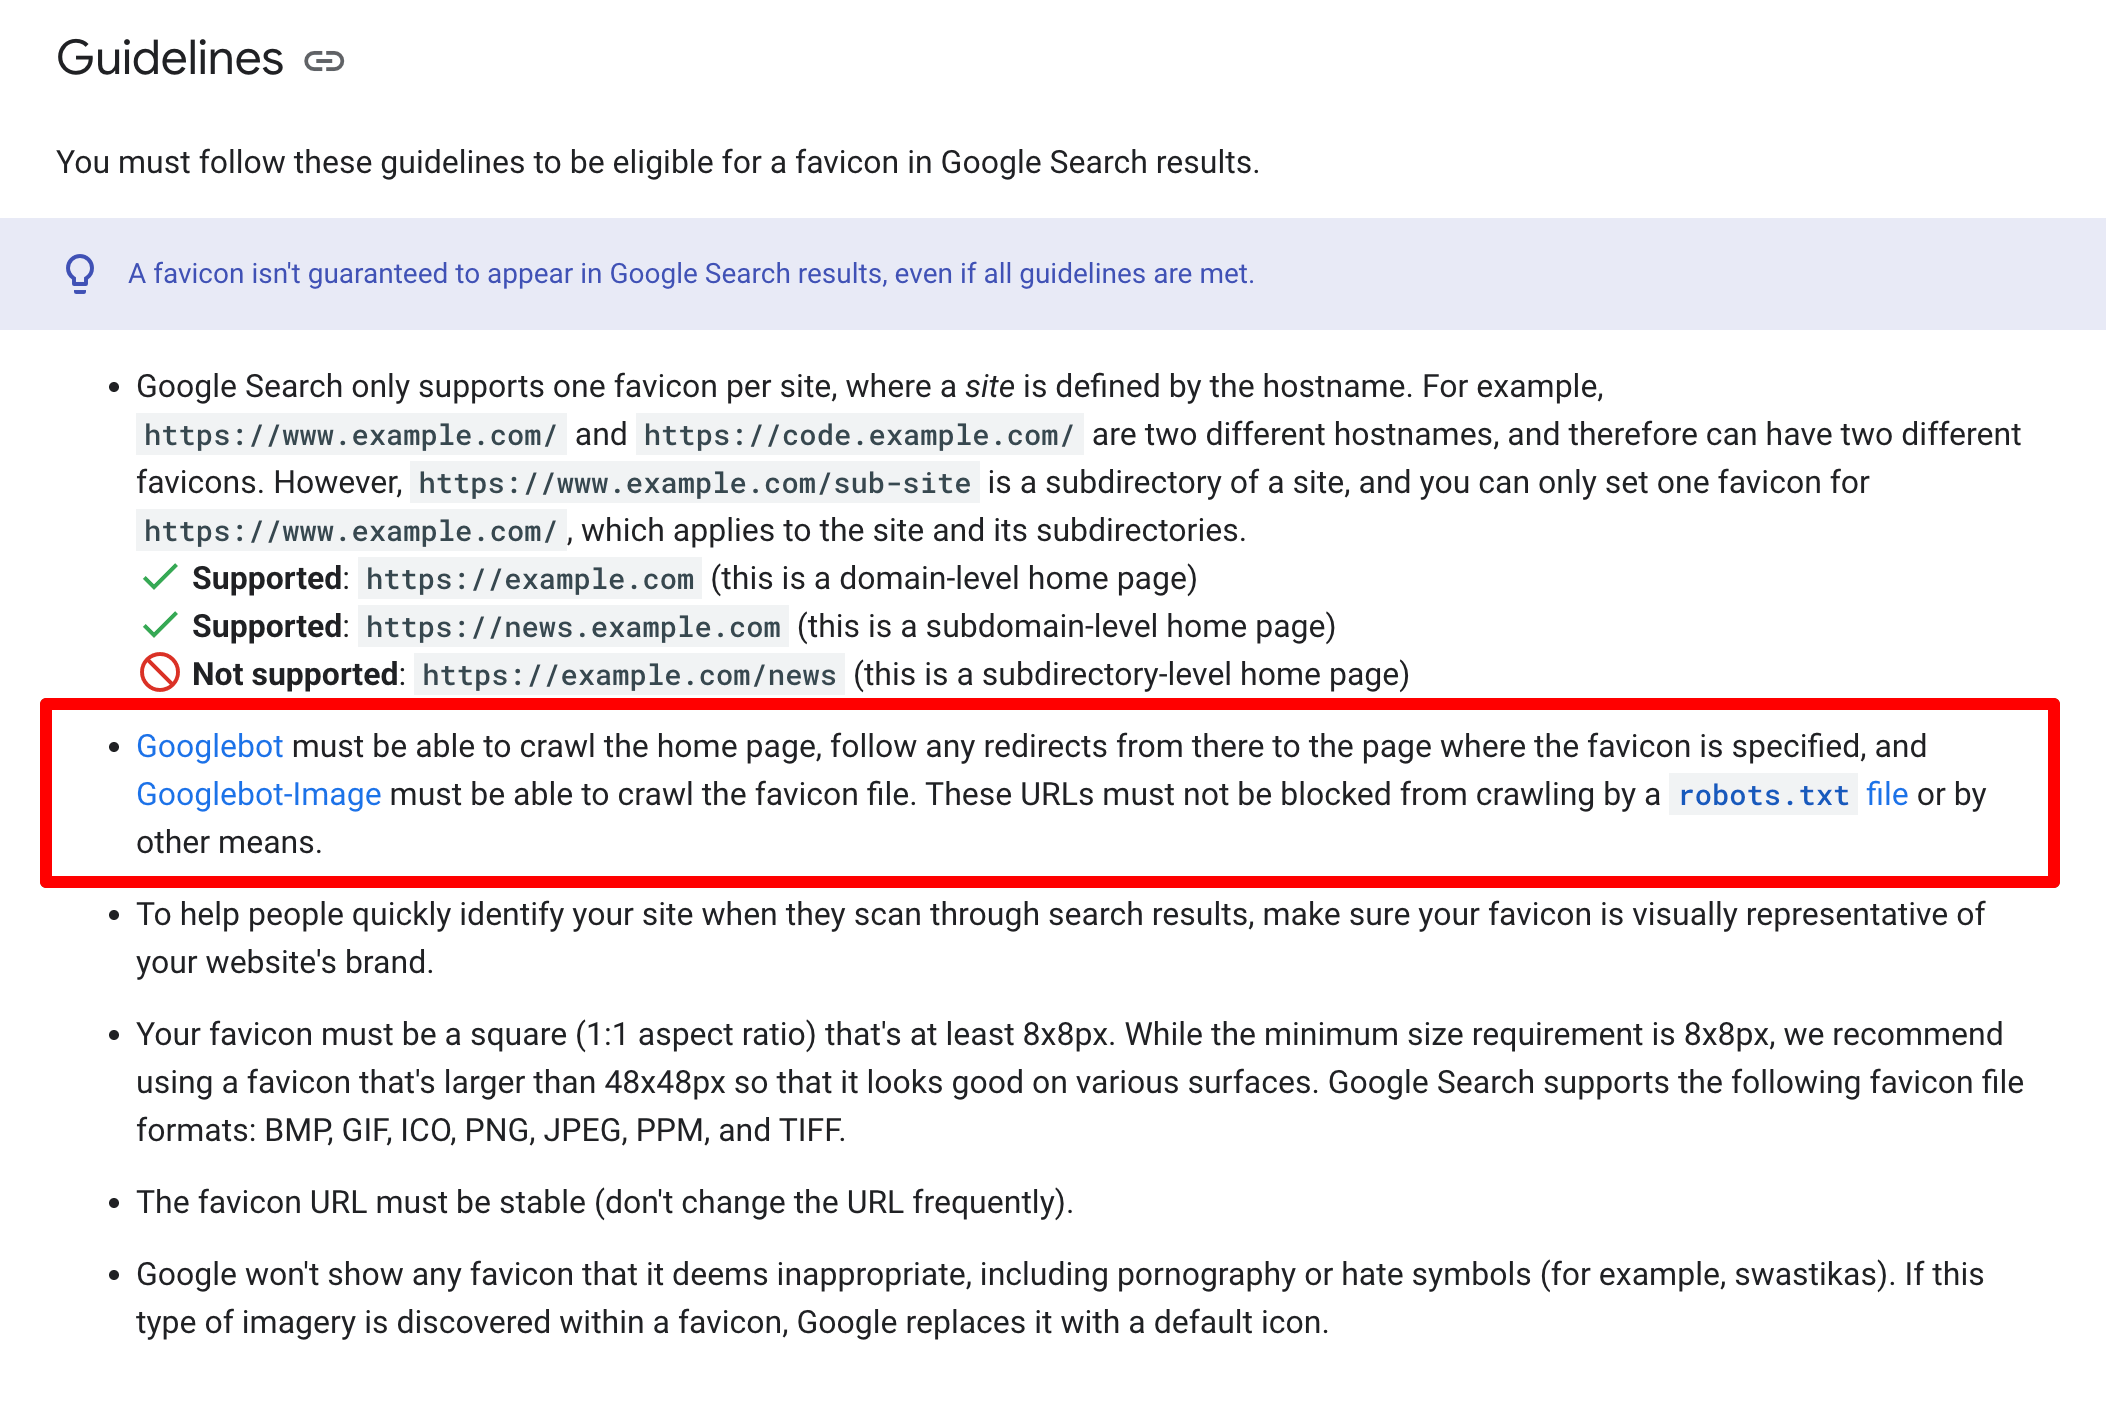
The updated documentation updated this one bullet point to say:
Googlebot must be able to crawl the home page, follow any redirects from there to the page where the favicon is specified, and Googlebot-Image must be able to crawl the favicon file. These URLs must not be blocked from crawling by a robots.txt file or by other means.
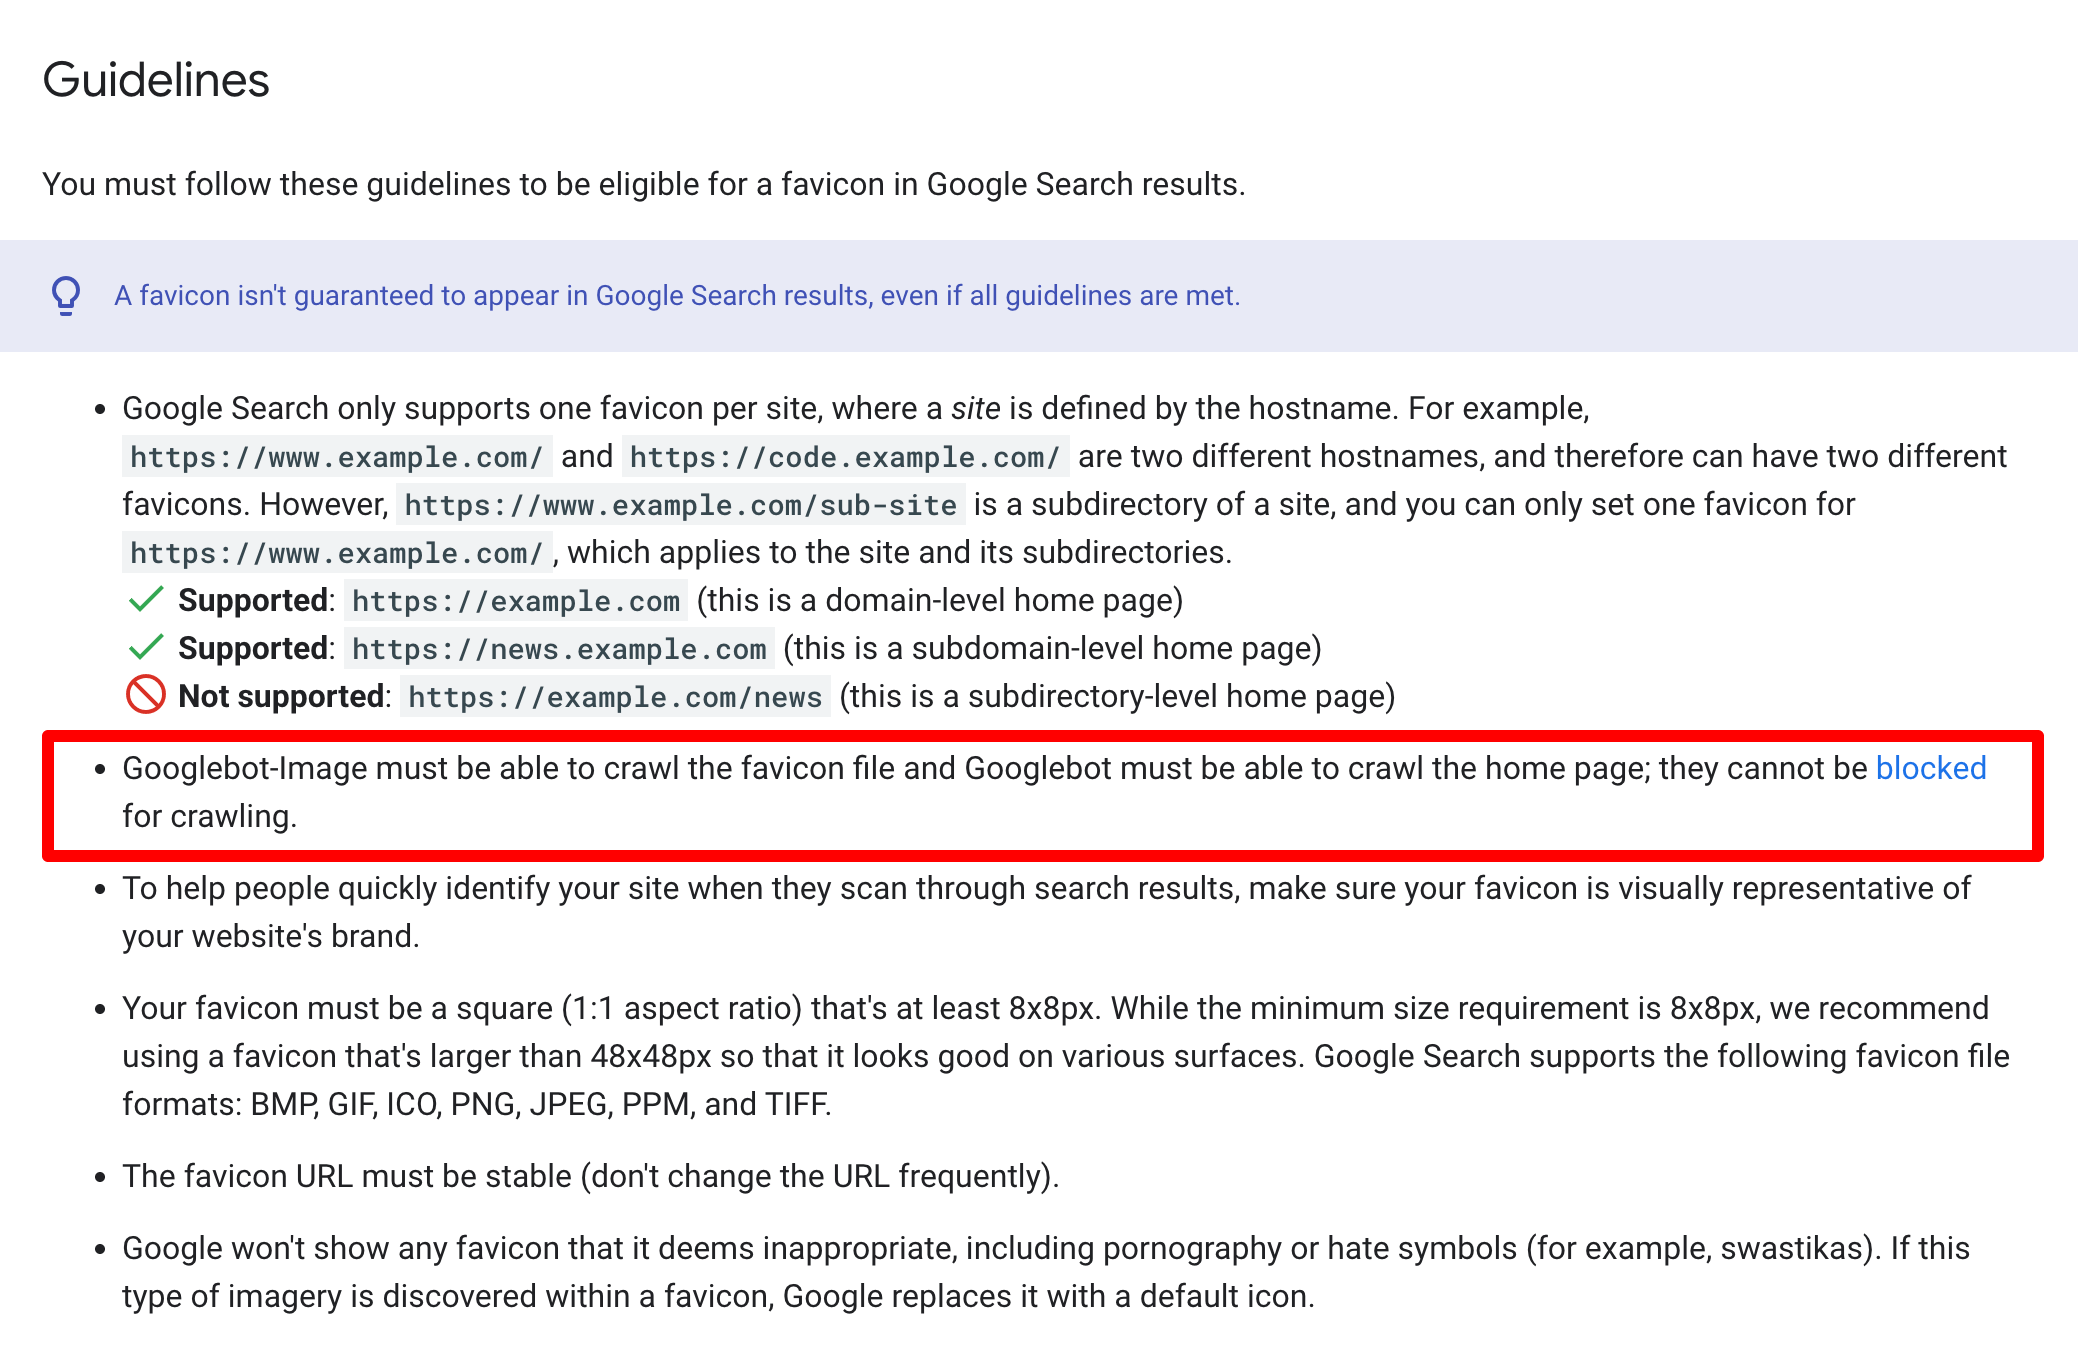
It previously said:
Googlebot-Image must be able to crawl the favicon file and Googlebot must be able to crawl the home page; they cannot be blocked for crawling.
This seems more like a clarification than anything else but it is a good clarification.
Here is a screenshot highlighting what changed - new document:
Old document:
So make sure to double-check that Google can reach the homepage, follow its redirects, and fetch the favicon.
Forum discussion at X.